Recurring SOC 2 findings often mean the previous repair left a cause unresolved, or the team cannot show that the control kept working. Trace the finding to its requirement, affected systems and owner. Then address the cause, verify the repair and keep checking the control as the company changes.
A closed remediation ticket can leave the team with the same finding at the next audit. The ticket may describe completed work while leaving open who checks the control afterward, what the check covers and where its results belong.
The cause of recurrence
A repeated finding can reflect a failed control, a missed part of the process or missing evidence of its operation. Compare the current finding with the earlier one. Identify the affected system, the expected condition and the observations that support each finding.
That comparison determines the repair. A control that failed needs attention to how it operates. A control without sufficient evidence needs a reliable record of the work. If both problems exist, include both in the remediation plan and assign responsibility for each.
A testable control condition
Write the control condition precisely enough to test it. The report or policy is the starting point. Its owner needs to specify what the language means in the affected systems, including which accounts an access-removal rule covers and when removal must occur.
This produces an expected result to compare with an observation. NIST's assessment guidance uses the comparison of intended and actual behavior when describing automated assessments. The same approach is useful here, with the company's own commitment defining the condition to test.
The affected systems
Include every system covered by the commitment when defining the repair. Removing a work identity can leave an application account active if that application accepts separate credentials. The team needs to find those accounts and identify who can remove them.
Check the system list against the applications now in use. An application added after the last audit may be absent, and an existing application may have another way to sign in. Record the agreed coverage so future checks include those routes.
The process behind the exception
Recurrence stops only when the repair reaches the cause of the problem. For a departed worker's account, review how the removal request moved through the team. Did anyone send it? Did it include the application? Did the requested removal succeed?
Removing that account addresses the immediate access problem. The answers determine whether the continuing process needs better departure notices, wider application coverage or a check after removal. Keep the cause in the record so the next review can test the relevant change.
Ownership after remediation
The control needs an owner after the remediation ticket closes. That owner coordinates the continuing checks and response. The person who changes a system may be different from the person responsible for the control, so record both responsibilities where the team manages the work.
Agree who receives a failed check, who can approve a repair and where overdue work goes for a decision. Include these arrangements when responsibilities change. Otherwise, a repaired control can lose its response path when the person who handled the audit moves to another role.
Checks between audits
Check timing should reflect how the control can fail and how quickly the team needs to respond. A configuration that changes with deployments needs observations around those changes. A scheduled review needs a check that it happened by the date in the commitment.
Continuous control monitoring can supply repeatable observations between audits. More frequent checks help only when someone can investigate their results and act. Set a schedule the team can operate, with a response window that reflects the consequence of leaving the control in a failed state.
Missing observations
Treat a control as unknown when the check has no current observation. The last passing result may predate a disconnected source or a failed check. Keep its date visible so the owner can distinguish that earlier result from the state now being assessed.
Someone must investigate the missing observation, whether by restoring the connection or inspecting the system directly. Record when observations stopped and keep the evidence available for that interval. Once checks resume, their results establish what was observed at those later times.
Approved repairs
Approval depends on understanding what the repair will change. Describe the proposed action and the access or service that must keep working. The owner can review that proposal through the appropriate route, such as a pull request, runbook or scoped action.
The decision may need more than a technical fix. An account could still serve a legitimate purpose, or a system could require a planned change window. Record the decision beside the finding, with any approved exception and responsibility for reviewing it again.
Verification before closure
A repair is ready for closure when a fresh check confirms its intended result. The action history tells the reviewer what the team did. A check of the changed system shows whether that action worked and whether required access or service remains available.
Keep the repair open if the check fails or the result is unavailable. When the check succeeds, save its date and observation beside the action and approval. The reviewer then has evidence for closing the repair and a result against which to compare later observations.
Evidence through the audit period
A repair record explains one correction; the continuing history explains what happened afterward. Keep both available to the reviewer. Later checks should show whether the control continued to operate, with the owner's accepted exceptions and the team's responses to any further failures.
In ZeroTB, the Verified Control Record holds the commitment, before-and-after state, action, approval and verification. The team can use that record to explain the correction without reconstructing it from messages. Subsequent check results document the control's operation after that correction.
Testing the revised process during the next change
Test the revised process when the next relevant change occurs. For an account-removal finding, follow the next departure through the affected applications. Check the notice sent to each responsible team, the actions it completed and the evidence recorded within the agreed timing.
Another failure at the same step is a reason to revisit the cause with fresh evidence. It identifies where further work is needed. A control review can help establish the condition behind the recurring finding and the work needed to restore the control.
Example of preventing missed account removal
An account-removal process needs to reach applications that keep their own credentials. In this example, a departed contractor still has access to one application. The team corrects the account and adds that application to the departure process, then checks the next departure.
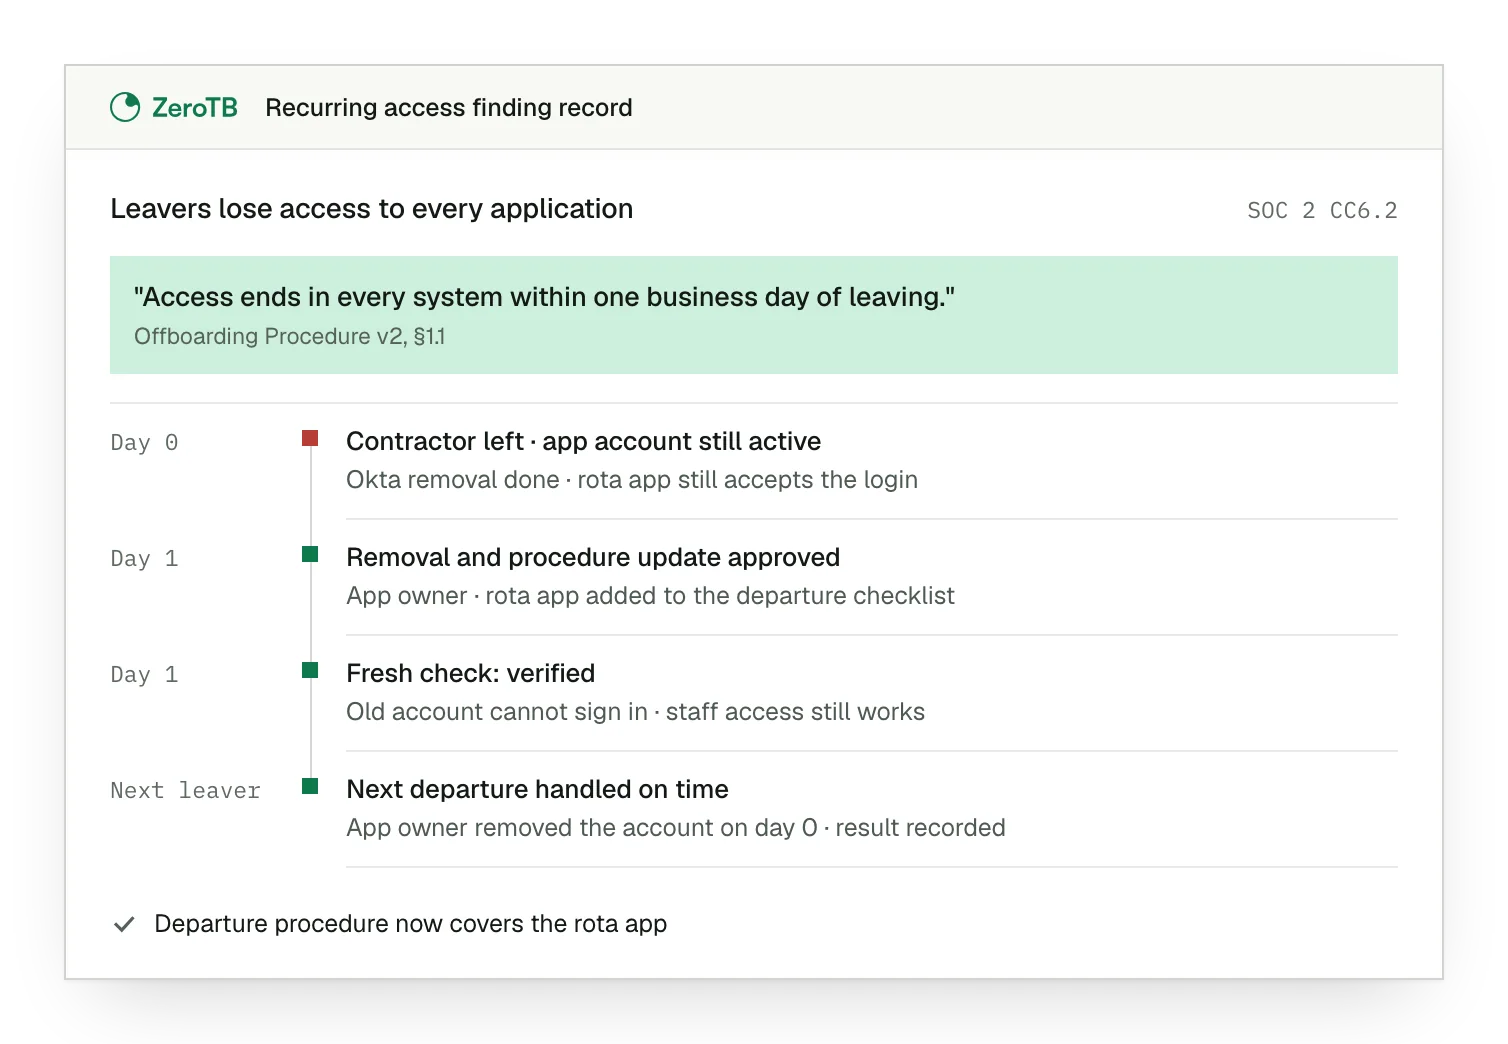
Missed application account. The departure record shows completed identity removal, while the application still accepts the contractor's credentials.
Approved process repair. The application owner approves account removal and adds the missing application to the departure procedure.
Confirmed access removal. A fresh check confirms the old account cannot sign in and required staff access remains available.
Next departure checked. The application owner receives the next departure notice, completes removal and records the result on time.
Recurring finding review checklist
Read both findings and their observations to locate the failure in the control, its coverage or its evidence.
Identify the systems covered by the requirement and the result a check must show before closure.
Record who owns the control after closure, who approves repairs and who investigates failed or missing checks.
Inspect the system after the change, then keep the observation beside the approved action and any exception.
Follow the next change through the revised process and check whether the expected actions and evidence are complete.
Sources
- NIST, Risk Management Framework: Assess step, updated September 23, 2026.
Related pages
Control operations
Explore how ongoing control work connects checks, approved corrections and evidence after the audit ends.
SOC 2 automation
Read how repeatable checks and repairs fit alongside the decisions that control owners still make.
Healthtech compliance
See how control operations support healthtech teams managing commitments across their systems and compliance programs.
Start with the Pilot
The eight-week Pilot maps up to 25 commitments and takes two real control gaps through approved repair and verified restoration. Talk with our team about recurring findings and the work needed to keep those controls operating.